Technology
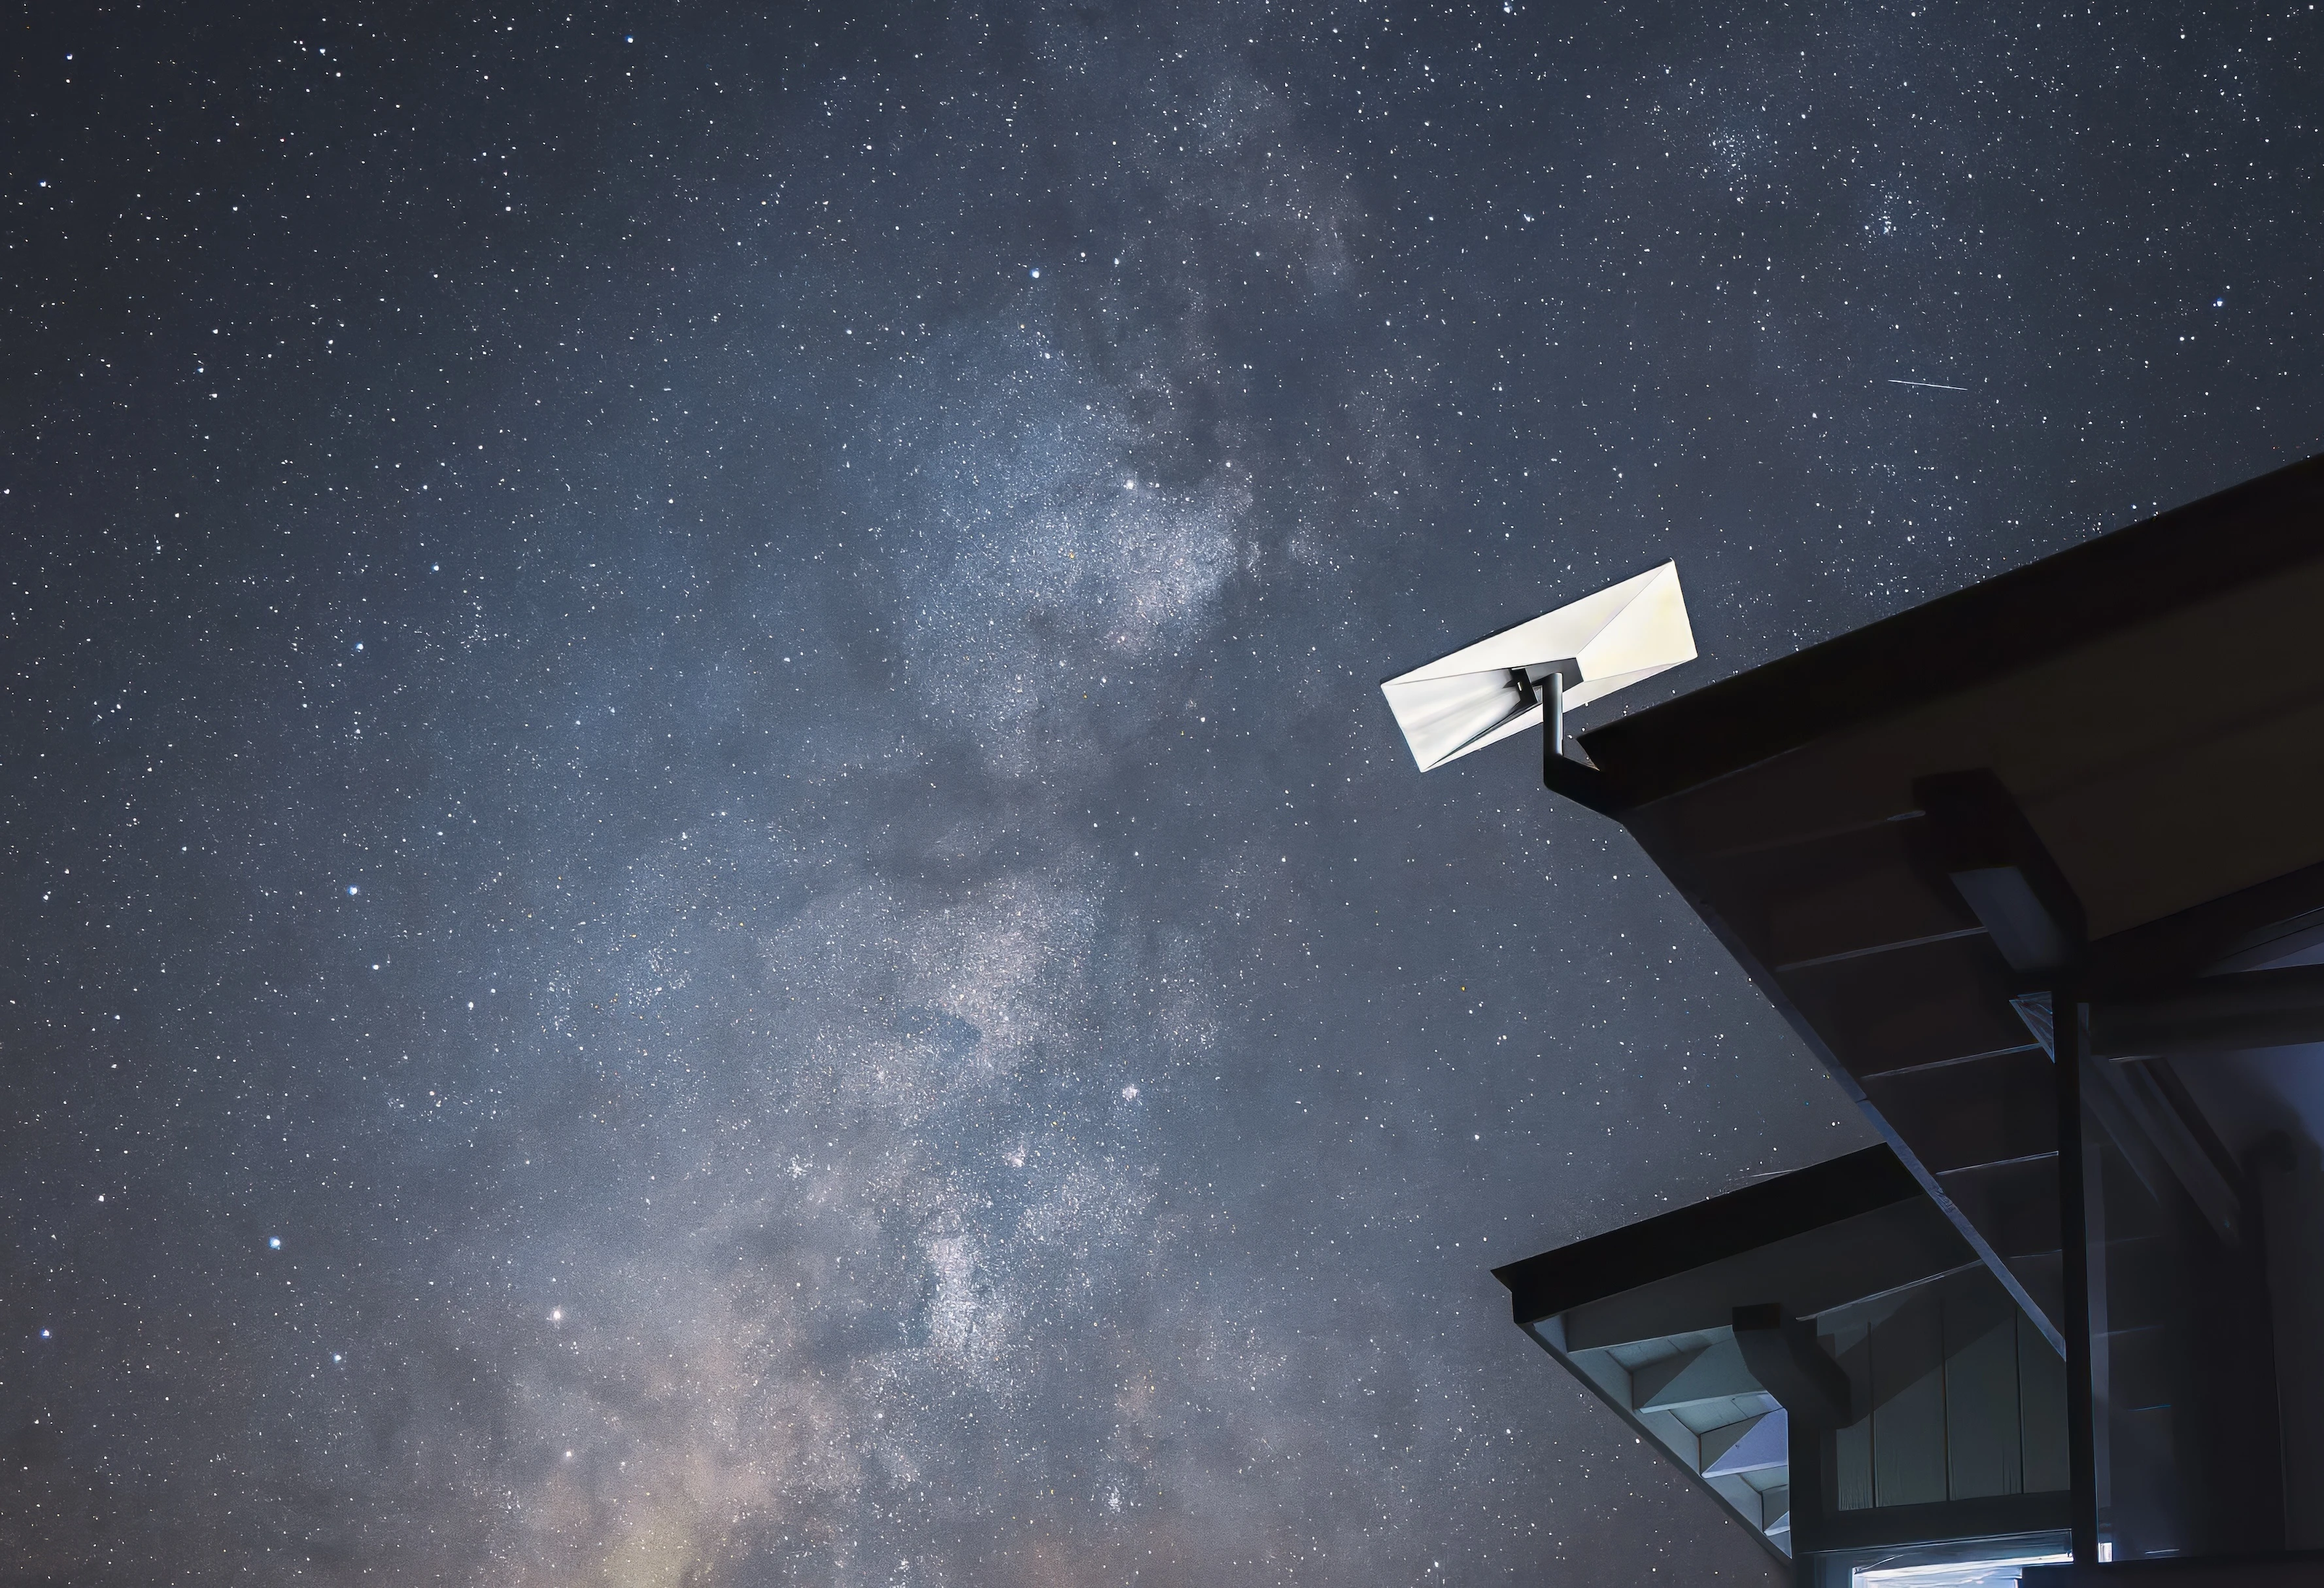
Starlink Mini 2
By Katherine Langford
Advertisement · Why this ad?
Marcus manages the day-to-day editorial workflow across all brands, coordinating coverage assignments and ensuring editorial standards are met. He previously served as city editor at the Pioneer Press and holds a degree in Political Science from Carleton College.
More from Marcus →
What objective is reasoning solving? Reasoning as pathfinding in token space. Contents There’s an intuitive but simplified picture of reasoning: let a model think for longer, and it’ll be more likely to be correct. This aligns well with our human intuition: spend more time and effort on thinking and it’s more likely that we’ll arrive at a correct answer. But this picture doesn’t seem to explain everything. During RL training, models learn to write longer chains of thought, and they get more accurate as they do. Yet if you take a trained model and force any one chain to run longer, it helps for a while, then stops helping. 1 Sometimes the answer even gets worse , as if it’s overthinking. 2 If a chain of thought were truly converging toward some optimum, more steps shouldn’t make it worse. So is it really the length of each chain that helps at inference time? Or is it something more subtle? This post is my attempt to clarify this confusion (mostly for myself) by looking at reasoning as pathfinding through token space. We’ll see that RL maximizes the probability of finding a path from $x$ to $\Scal_x$, but individual paths are not guaranteed to converge to the correct answer. As a bonus, this perspective clarifies some odd observations about reasoning models, like unfaithful chains of thought and reward hacking. Reasoning as pathfinding # Ask a reasoning model the same math problem ten times and you’ll get ten different chains of thought. Rather than thinking of reasoning as one mysterious process heading toward an answer, let’s think of it as pathfinding in token space. There are many paths from the problem to a correct answer, and the model traverses one of them with each sample. Consider the problem: “what’s $1 + 2 + 3 + \cdots + 10$”? One solution is to add the numbers one at a time: 1, 3, 6, 10, and so on up to 55. Another way is to pair them from the outside in: $1 + 10$, $2 + 9$, $3 + 8$, $4 + 7$ and $5 + 6$ each make 11, and five pairs of 11 make 55. Both of these paths land on the correct answer, 55. We can think about reasoning as following this general pattern. We are given a starting point, the prompt, which we’ll call $x$. We want to find a path $z$ that starts from $x$ and ends at a correct answer $y$. To tell whether a path lands in the right place, we assume we have a verifier $r(x, y)$ that returns 1 if $y$ is correct and 0 if it isn’t. So given a starting point $x$, we want to find a path of tokens $z$ that lands in the set $$\Scal_x = \{y : r(x, y) = 1\}.$$ The figure at the top of this post sketches this picture. Each gray line is a sampled path: it starts from the prompt on the left, meanders in token space by sampling $z$, with some of these paths landing in $\Scal_x$. Since many paths land in $\Scal_x$, the success probability adds up over all of them. Let $\pi(z \mid x)$ be the probability that the model generates the path $z$ given the prompt $x$, and $y(z)$ for the final answer at the end of $z$. The probability of success is the probability of generating each path, times the probability that path lands in $\Scal_x$, summed over every path: $$p_x = \prob{\text{a path lands in } \Scal_x \mid x} = \sum_{z} \underbrace{\pi(z \mid x)}_{\text{samples path } z}\; \underbrace{\prob{y(z) \in \Scal_x \mid z}}_{\text{path } z \text{ lands in }\Scal_x}.$$ The second factor is just 1 if the path lands in $\Scal_x$ and 0 if it doesn’t, so we sum only the probability of paths that land in $\Scal_x$: $$p_x = \sum_{z} \pi(z \mid x)\, \ind{y(z) \in \Scal_x} = \sum_{z \,:\, y(z) \in \Scal_x} \pi(z \mid x).$$ We’ll call $p_x$ the success probability . Maximizing this probability means our model will be more likely to sample a path that lands in $\Scal_x$. Note that there are two ways of increasing this probability. Either the model can sample multiple paths to the same answer, each with a small probability, or the model can sample a single path to the answer with a very high probability. The success probability doesn’t care which one we get, but in practice we might want to prioritize specific paths or ensure diversity in the samples 3 . How do we boost our success probability? # Best-of-$k$ sampling # The simplest way to pathfind is to have the model $\pi$ keep sampling paths $z$ until one lands in $\Scal_x$. Since we assumed we had a verifier, we can do best-of-$k$ sampling, which samples $k$ paths and looks for a success. Each path misses with probability $1 - p_x$, so all $k$ miss with probability $(1-p_x)^k$, and the success probability rises from $p_x$ to $$\prob{\text{at least one of } k \text{ paths lands in } \Scal_x \mid x} = 1 - \underbrace{(1-p_x)^k}_{\text{all } k \text{ paths miss}}.$$ This is a guaranteed axis of compute-scaling. As long as $p_x > 0$, the success probability increases monotonically as we sample more paths, so spending more compute on more samples always helps, as seen early on by Brown et al. 2024 . However, the scaling here is over the number of samples rather than the length of the paths (thinking longer). Train the model to generate better samples # So far the model was fixed, so $p_x$ was fixed too. Can we change the model to increase $p_x$ itself? Here’s a simple way to do this. Collect many prompts whose answers we can check. For each one, sample some paths from the model. We keep the paths that land in $\Scal_x$, and train the model on the ones we kept. Then repeat. Each round, we train the model to put more weight on the successful paths that it sampled. This loop is called rejection-sampling fine-tuning, and STaR was an early version of it for reasoning. RL with a verifiable reward, which is how today’s reasoning models are trained, turns out to do almost the same thing. Let $\pi_\theta$ be the model with weights $\theta$. Then since $r(x, y(z)) = 1$ exactly when $y(z) \in \Scal_x$: $$ \begin{aligned} p_x &= \sum_{z \,:\, y(z) \in \Scal_x} \pi_\theta(z \mid x) \\ &= \sum_{z} \pi_\theta(z \mid x)\, \ind{y(z) \in \Scal_x} \\ &= \sum_{z} \pi_\theta(z \mid x)\, r(x, y(z)) \\ &= \ev[z \sim \pi_\theta(\cdot \mid x)]{r(x, y(z))}, \end{aligned} $$ meaning the expected binary reward is exactly the success probability $p_x$. Computing the gradient of the success probability via the log-derivative trick, we arrive at $$\grad_\theta\, p_x = \ev[z \sim \pi_\theta(\cdot \mid x)]{r(x, y(z))\, \grad_\theta \log \pi_\theta(z \mid x)},$$ which is exactly the policy gradient, also called the REINFORCE estimator. Now estimate this gradient with $N$ sampled paths $z_1, \dots, z_N$. The paths that failed have $r = 0$ and disappear, while the paths that land in $\Scal_x$ have $r = 1$. If $M$ of the $N$ paths succeed, the estimate is $$\grad_\theta\, p_x \approx \frac{1}{N} \sum_{i \,:\, \text{landed}} \grad_\theta \log \pi_\theta(z_i \mid x) = \underbrace{\frac{M}{N}}_{\text{success rate}} \cdot \underbrace{\frac{1}{M} \sum_{i \,:\, \text{landed}} \grad_\theta \log \pi_\theta(z_i \mid x)}_{\text{log likelihood of the successful paths}}.$$ This gradient involves two terms: the empirical success rate $M/N$ and the average log likelihood of the successful paths. In other words, a step of REINFORCE with a binary reward is a step of rejection-sampling fine-tuning on the model’s own sampled paths, scaled by the current success rate $M/N$. This also explains the first observation from the intro, that chains of thought get longer during RL training. Each step pulls the model toward the paths that landed, so if the paths that succeeded tended to be longer than the ones that failed (e.g. because they include backtracking behavior, gather more feedback from the environment, or just dumb luck), the model will learn to write longer paths. Amortization and generalization # During RL training, we spend a lot of compute to search for good paths and then we train the model to generate those paths directly. Once trained, the model can produce the answer without spending all th